cuda-solver-lab
Conjugate Gradient and Jacobi solvers for the 2D Poisson equation: serial C++, OpenMP, hand-written CUDA kernels, cuSPARSE + cuBLAS reference and Fortran OpenACC, profiled with Nsight Compute. By Pavan Yadav Annappa.
Code on GitHubDev log (bugs found) README and method
Plots

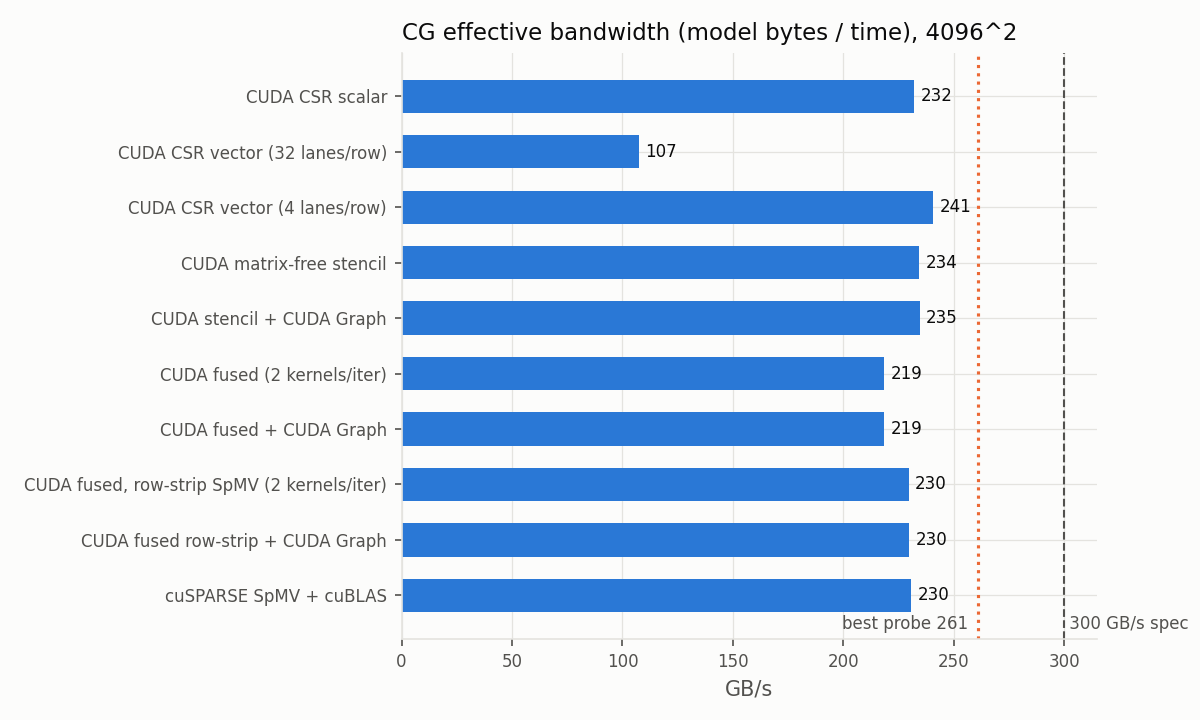
Results
All numbers: measured on NVIDIA L4, CUDA 12.9, 2026-10-03. Generated by scripts/make_report.py from results/raw/.
Hardware ceilings (bw_probe)
| probe | best of 20 | % of 300 GB/s spec |
|---|---|---|
| copy_f64 | 232.4 GB/s | 77.5 % |
| copy_f64x2 | 233.3 GB/s | 77.8 % |
| triad_f64 | 237.8 GB/s | 79.3 % |
| read_f64 | 261.0 GB/s | 87.0 % |
| write_f64 | 241.2 GB/s | 80.4 % |
| memcpy_d2d | 232.3 GB/s | 77.5 % |
| fma_f64 | 398 GFLOP/s | |
| fma_f32 | 25,415 GFLOP/s |
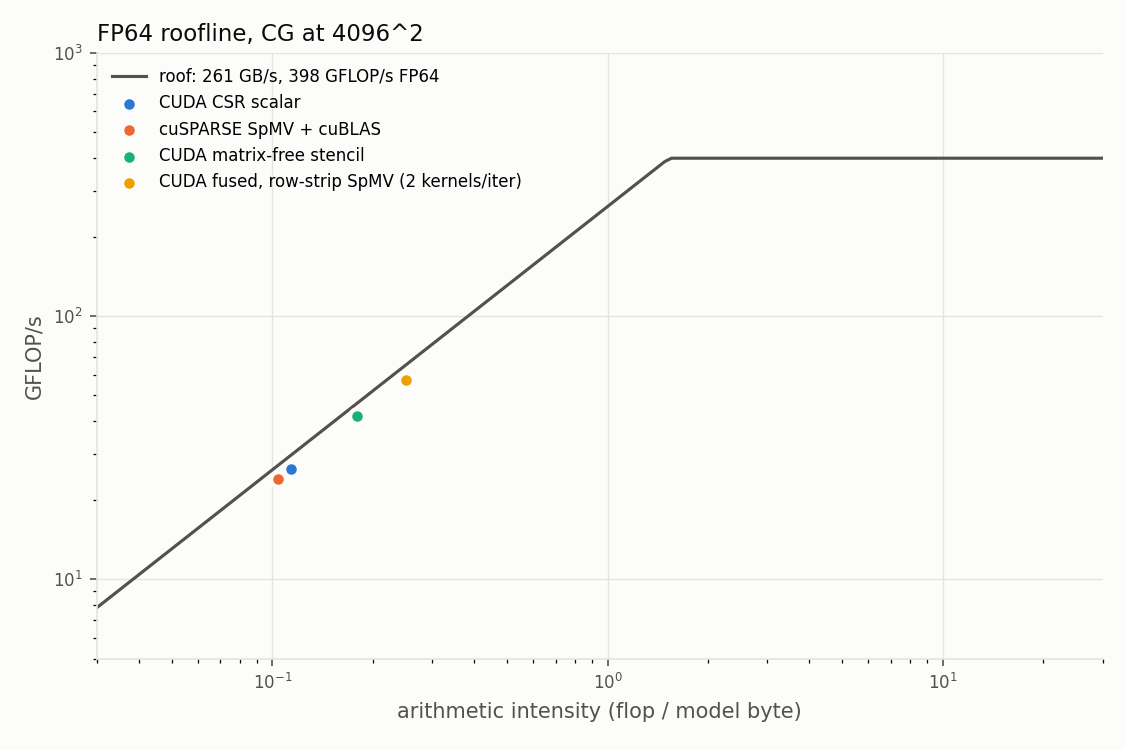
Best measured bandwidth: 261.0 GB/s (87.0 % of the 300 GB/s datasheet value; ECC is enabled on this GPU). FP64 FMA peak: 398 GFLOP/s (FP32/FP64 = 64). FP64 ridge point = 398 / 261.0 = 1.53 flop/byte.
CG: time per iteration (ms), fixed iteration count
| implementation | 256^2 | 512^2 | 1024^2 | 2048^2 | 4096^2 |
|---|---|---|---|---|---|
| CPU serial (CSR) | 0.355 | 1.456 | 6.911 | 31.628 | 149.644 |
| CPU OpenMP 16 thr (CSR) | 0.051 | 0.141 | 0.938 | 9.427 | 47.801 |
| CPU OpenMP 32 thr (CSR) | 0.069 | 0.145 | 1.013 | 10.022 | 52.209 |
| Fortran OpenACC gfortran, GPU | 2.703 | 3.644 | 3.585 | 4.310 | 9.152 |
| Fortran OpenACC nvfortran, GPU | 0.064 | 0.083 | 0.182 | 1.711 | 7.014 |
| Fortran do concurrent nvfortran, GPU | 0.037 | 0.057 | 0.167 | 1.795 | 7.791 |
| CUDA CSR scalar | 0.026 | 0.046 | 0.523 | 2.860 | 12.718 |
| CUDA CSR vector (32 lanes/row) | 0.089 | 0.296 | 1.347 | 6.371 | 27.520 |
| CUDA CSR vector (4 lanes/row) | 0.031 | 0.059 | 0.528 | 2.821 | 12.273 |
| CUDA matrix-free stencil | 0.025 | 0.038 | 0.114 | 1.600 | 8.018 |
| CUDA stencil + CUDA Graph | 0.021 | 0.034 | 0.121 | 1.592 | 8.013 |
| CUDA fused (2 kernels/iter) | 0.018 | 0.033 | 0.124 | 1.437 | 6.141 |
| CUDA fused + CUDA Graph | 0.017 | 0.032 | 0.131 | 1.437 | 6.143 |
| CUDA fused, row-strip SpMV (2 kernels/iter) | 0.017 | 0.032 | 0.113 | 1.468 | 5.848 |
| CUDA fused row-strip + CUDA Graph | 0.015 | 0.030 | 0.107 | 1.470 | 5.841 |
| cuSPARSE SpMV + cuBLAS | 0.045 | 0.080 | 0.392 | 3.176 | 13.975 |
CG at 4096^2 (16,777,216 unknowns): bandwidth, roofline, speedups
| implementation | ms/iter | model MB/iter | eff. GB/s | % of 300 GB/s | GFLOP/s | flop/byte | vs CPU serial | vs cuSPARSE |
|---|---|---|---|---|---|---|---|---|
| CPU serial (CSR) | 149.644 | 2,953 | 19.7 | - | 2.2 | 0.114 | 1.0x | 0.09x |
| CPU OpenMP 16 thr (CSR) | 47.801 | 2,953 | 61.8 | - | 7.0 | 0.114 | 3.1x | 0.29x |
| CPU OpenMP 32 thr (CSR) | 52.209 | 2,953 | 56.6 | - | 6.4 | 0.114 | 2.9x | 0.27x |
| Fortran OpenACC gfortran, GPU | 9.152 | 1,476 | 161.3 | 53.8 | 36.7 | 0.227 | 16.4x | 1.53x |
| Fortran OpenACC nvfortran, GPU | 7.014 | 1,476 | 210.5 | 70.2 | 47.8 | 0.227 | 21.3x | 1.99x |
| Fortran do concurrent nvfortran, GPU | 7.791 | 1,476 | 189.5 | 63.2 | 43.1 | 0.227 | 19.2x | 1.79x |
| CUDA CSR scalar | 12.718 | 2,953 | 232.2 | 77.4 | 26.4 | 0.114 | 11.8x | 1.10x |
| CUDA CSR vector (32 lanes/row) | 27.520 | 2,953 | 107.3 | 35.8 | 12.2 | 0.114 | 5.4x | 0.51x |
| CUDA CSR vector (4 lanes/row) | 12.273 | 2,953 | 240.6 | 80.2 | 27.3 | 0.114 | 12.2x | 1.14x |
| CUDA matrix-free stencil | 8.018 | 1,879 | 234.4 | 78.1 | 41.8 | 0.179 | 18.7x | 1.74x |
| CUDA stencil + CUDA Graph | 8.013 | 1,879 | 234.5 | 78.2 | 41.9 | 0.179 | 18.7x | 1.74x |
| CUDA fused (2 kernels/iter) | 6.141 | 1,342 | 218.6 | 72.9 | 54.6 | 0.250 | 24.4x | 2.28x |
| CUDA fused + CUDA Graph | 6.143 | 1,342 | 218.5 | 72.8 | 54.6 | 0.250 | 24.4x | 2.28x |
| CUDA fused, row-strip SpMV (2 kernels/iter) | 5.848 | 1,342 | 229.5 | 76.5 | 57.4 | 0.250 | 25.6x | 2.39x |
| CUDA fused row-strip + CUDA Graph | 5.841 | 1,342 | 229.8 | 76.6 | 57.4 | 0.250 | 25.6x | 2.39x |
| cuSPARSE SpMV + cuBLAS | 13.975 | 3,221 | 230.5 | 76.8 | 24.0 | 0.104 | 10.7x | 1.00x |
Roofline: the fused CG iteration does 0.25 flop/byte against a ridge point of 1.53 flop/byte, so the attainable rate is bandwidth x intensity = 65 GFLOP/s, 16.4 % of FP64 peak: CG is memory bound by a factor of 6.1, and the only lever is bytes moved per iteration.
Speedups at 4096^2 (best GPU variant = CUDA fused row-strip + CUDA Graph): 25.6x vs CPU serial, 8.2x vs best CPU OpenMP, 2.39x vs cuSPARSE + cuBLAS; CPU OpenMP vs serial: 3.1x.
Fortran at 4096^2: gfortran OpenACC 9.152 ms/iter; Fortran OpenACC nvfortran, GPU 7.014 ms/iter (1.30x faster than gfortran, 1.20x the time of the best CUDA variant, 6.8x faster than best CPU OpenMP); Fortran do concurrent nvfortran, GPU 7.791 ms/iter (1.17x faster than gfortran, 1.33x the time of the best CUDA variant, 6.1x faster than best CPU OpenMP).
Launch-bound regime (256^2, everything L2 resident): stencil 24.8 us/iter -> 20.7 us with a CUDA Graph (1.20x); fused 17.9 -> 16.7 us (1.08x). At 4096^2 the graph changes stencil by 1.001x (launch cost is hidden behind ms-long kernels).
CG time to solution, 1024^2, relative residual 1e-8
| implementation | iterations | seconds | true rel. residual | max error vs analytic | vs CPU serial |
|---|---|---|---|---|---|
| CUDA CSR scalar | 3152 | 1.681 | 9.95e-09 | 8.857e-08 | 12.9x |
| CUDA CSR vector (32 lanes/row) | 3152 | 4.454 | 9.95e-09 | 8.857e-08 | 4.9x |
| CUDA CSR vector (4 lanes/row) | 3152 | 1.697 | 9.95e-09 | 8.857e-08 | 12.8x |
| CUDA matrix-free stencil | 3152 | 0.445 | 9.95e-09 | 8.857e-08 | 48.8x |
| CUDA stencil + CUDA Graph | 3160 | 0.418 | 9.28e-09 | 8.857e-08 | 51.9x |
| CUDA fused (2 kernels/iter) | 3152 | 0.461 | 9.95e-09 | 8.857e-08 | 47.1x |
| CUDA fused + CUDA Graph | 3160 | 0.450 | 9.28e-09 | 8.857e-08 | 48.1x |
| CUDA fused, row-strip SpMV (2 kernels/iter) | 3152 | 0.400 | 9.95e-09 | 8.857e-08 | 54.3x |
| CUDA fused row-strip + CUDA Graph | 3160 | 0.392 | 9.28e-09 | 8.857e-08 | 55.2x |
| cuSPARSE SpMV + cuBLAS | 3152 | 1.296 | 9.95e-09 | 8.857e-08 | 16.7x |
| CPU serial (CSR) | 3152 | 21.679 | 9.95e-09 | 8.857e-08 | 1.0x |
| CPU OpenMP 16 thr (CSR) | 3152 | 2.855 | 9.95e-09 | 8.857e-08 | 7.6x |
| Fortran OpenACC gfortran, GPU | 3152 | 11.373 | 9.95e-09 | 8.857e-08 | 1.9x |
| Fortran OpenACC nvfortran, GPU | 3152 | 0.599 | 9.95e-09 | 8.857e-08 | 36.2x |
| Fortran do concurrent nvfortran, GPU | 3152 | 0.551 | 9.95e-09 | 8.857e-08 | 39.3x |
GPU solves check the residual every iteration (graph variants every 10), which adds a device-to-host copy per check; it is included in these times.
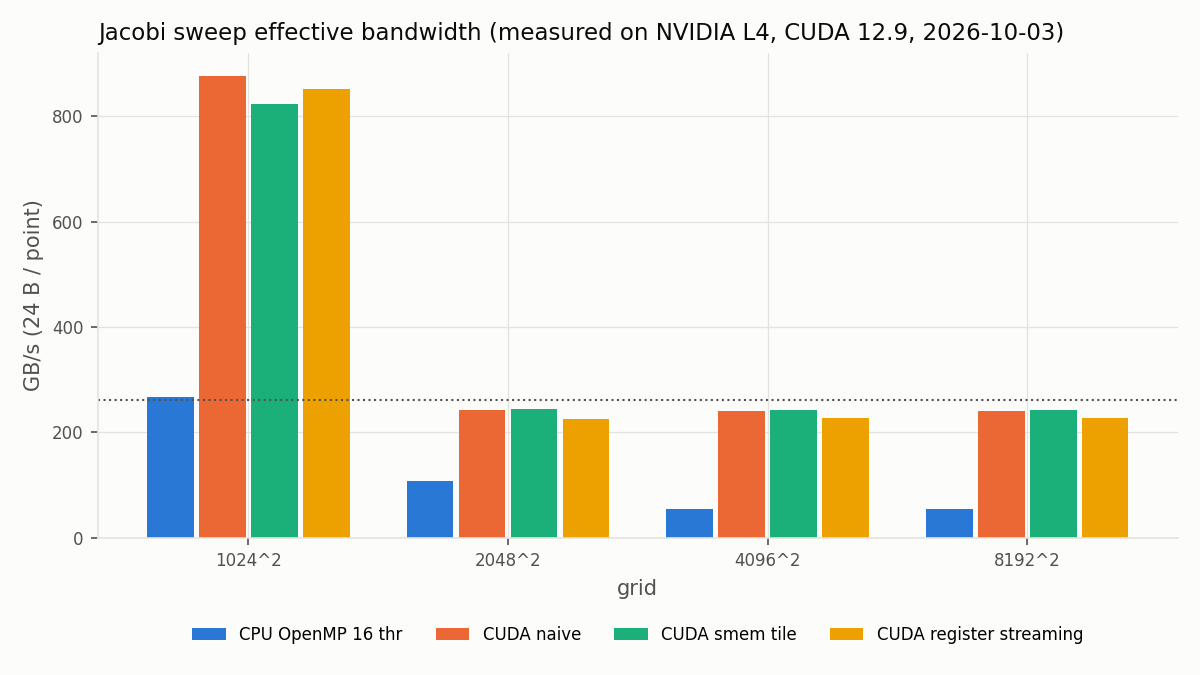
Jacobi sweep: effective bandwidth (GB/s, 24 B per point update)
| kernel | 1024^2 | 2048^2 | 4096^2 | 8192^2 |
|---|---|---|---|---|
| CPU OpenMP 16 threads | 266.6 (0.094 ms) | 107.0 (0.941 ms) | 54.6 (7.370 ms) | 54.0 (29.825 ms) |
| CUDA naive (global loads) | 875.8 (0.029 ms) | 242.7 (0.415 ms) | 241.5 (1.667 ms) | 241.0 (6.682 ms) |
| CUDA shared-memory tile 32x8 | 822.5 (0.031 ms) | 245.3 (0.410 ms) | 243.0 (1.657 ms) | 243.2 (6.623 ms) |
| CUDA register streaming (16 rows/thread) | 850.4 (0.030 ms) | 225.4 (0.447 ms) | 227.7 (1.768 ms) | 227.6 (7.075 ms) |
Nsight Compute, one launch per kernel at 4096^2 (ncu --set full)
| profile | duration ms | DRAM % of peak | DRAM GB/s | DRAM read MB | DRAM write MB | achieved occ. % | theor. occ. % | sectors/request (global ld) | L2 hit % | regs/thread |
|---|---|---|---|---|---|---|---|---|---|---|
| spmv_csr_scalar | 5.923 | 95.0 | 284.6 | 1,529 | 157 | 98.8 | 100 | 18.41 | 47.2 | 40 |
| spmv_csr_vector32 | 45.625 | 19.4 | 58.2 | 2,445 | 211 | 80.8 | 100 | 1.80 | 41.3 | 39 |
| spmv_csr_vector4 | 5.359 | 96.1 | 288.1 | 1,392 | 152 | 99.8 | 100 | 5.09 | 28.9 | 40 |
| cusparse_spmv | 5.443 | 95.7 | 286.9 | 1,423 | 138 | 72.8 | 75 | 5.92 | 28.0 | 56 |
| spmv_stencil | 1.360 | 82.7 | 247.9 | 199 | 138 | 84.9 | 100 | 8.40 | 69.1 | 34 |
| dot_finalize | 1.072 | 96.5 | 289.3 | 308 | 2 | 96.4 | 100 | 8.00 | 0.1 | 36 |
| fused_p_spmv_dot | 3.279 | 85.5 | 256.3 | 539 | 301 | 91.2 | 100 | 8.39 | 58.4 | 40 |
| fused_rows_p_spmv_dot | 2.459 | 85.9 | 257.5 | 336 | 297 | 98.5 | 100 | 3.43 | 52.3 | 36 |
| fused_xr_dot | 3.426 | 87.8 | 263.0 | 614 | 287 | 98.4 | 100 | 7.99 | 33.4 | 38 |
First fused kernel, model traffic 537 MB (read r, p_old; write p_new, Ap): the 1D grid-stride version moves 840 MB (reads 2.01x the model), the row-strip version 633 MB (reads 1.25x); kernel time 3.28 -> 2.46 ms under ncu.
ncu locks clocks to base during profiling, so durations differ slightly from the timed runs. Sectors/request is averaged over all global loads of the kernel: a fully coalesced warp load touches 8 sectors (32 B each) for 8-byte values and 4 for 4-byte values; higher means scattered accesses.
Unprivileged ncu on this host fails with:
==ERROR== ERR_NVGPUCTRPERM - The user does not have permission to access NVIDIA GPU Performance Counters on the target device 0. For instructions on enabling permissions and to get more information see https://developer.nvidia.com/ERR_NVGPUCTRPERM
(RmProfilingAdminOnly=1), so the profiles were taken with passwordless sudo.
Nsight Systems kernel census, cuSPARSE + cuBLAS path (n = 1024, 10 warm-up + 100 timed iterations)
| kernel | instances | per iteration |
|---|---|---|
| cusparse::csrmv_v3_kernel | 110 | 1 |
| axpy_kernel_ref | 330 | 3 |
| dot_kernel | 220 | 2 |
| scal_kernel_ref | 110 | 1 |
| cusparse::vector_scalar_multiply_kernel | 110 | 1 |
| reduce_1Block_kernel | 220 | 2 |
| cusparse:: |
110 | 1 |
| cgk::lib_beta(cgk::Scalars *) | 110 | 1 |
| cgk::lib_alpha(cgk::Scalars *) | 110 | 1 |
13 GPU kernels per CG iteration for the library path vs 2 for the fused variant.
Nsight Systems, Fortran GPU builds (n = 1024, 100 fixed iterations)
| build | kernel | per iteration | avg us |
|---|---|---|---|
| gfortran OpenACC | MAIN__$_omp_fn$0 | 1 | 1,528.9 |
| gfortran OpenACC | MAIN__$_omp_fn$1 | 1 | 1,518.3 |
| gfortran OpenACC | MAIN__$_omp_fn$2 | 1 | 13.6 |
| gfortran OpenACC | sum of kernel time per iteration: 3.061 ms | 3 | API calls/iter: cuMemAlloc_v2 3, cuMemFree_v2 3, cuStreamSynchronize 3 |
| nvfortran OpenACC | cg_acc_112_gpu | 1 | 47.8 |
| nvfortran OpenACC | cg_acc_123_gpu | 1 | 35.2 |
| nvfortran OpenACC | cg_acc_135_gpu | 1 | 14.1 |
| nvfortran OpenACC | cg_acc_123_gpu__red | 1 | 7.4 |
| nvfortran OpenACC | cg_acc_112_gpu__red | 1 | 6.9 |
| nvfortran OpenACC | sum of kernel time per iteration: 0.111 ms | 5 | API calls/iter: cuMemAlloc_v2 0, cuMemFree_v2 0, cuStreamSynchronize 10 |
| nvfortran do concurrent | cg_acc_87_gpu | 1 | 99.4 |
| nvfortran do concurrent | cg_acc_93_gpu | 1 | 84.0 |
| nvfortran do concurrent | cg_acc_100_gpu | 1 | 14.2 |
| nvfortran do concurrent | cg_acc_87_gpu__red | 1 | 9.2 |
| nvfortran do concurrent | cg_acc_93_gpu__red | 1 | 8.7 |
| nvfortran do concurrent | sum of kernel time per iteration: 0.215 ms | 5 | API calls/iter: cuMemAlloc_v2 0, cuMemFree_v2 0, cuStreamSynchronize 3 |
Kernel names are compiler generated: gfortran numbers the offloaded regions (MAIN__$_omp_fn$N), nvfortran names them by source line, with a __red kernel finishing each reduction. -Minfo compiler feedback for the nvfortran builds is in results/minfo/.
compute-sanitizer
43 of 44 runs clean (memcheck, racecheck, synccheck, initcheck x every CG variant + Jacobi).
Not clean: cg_cuda cusparse racecheck: RACECHECK SUMMARY: 100 hazards displayed (374 errors, 187 warnings).